
AI Sales Rep Productivity Governance in 2026 — Measure Activity Quality, Not Volume, Before the Agent Inflates the Score
Productivity governance precedes productivity scoring: write the control set before the AI score reaches a one-on-one, not after.
The direct answer
Productivity governance precedes productivity scoring: write the control set before the AI score reaches a one-on-one, not after. The five-control schema is the reconciliation line, the rep-authored baseline, the named executive ratifier, the documented human-review gate, and the written framework. Each control is documented before the AI score reaches a 1:1; each control is auditable quarter-over-quarter; each control is the operating definition of how the AI score is generated and reviewed.
The sequence matters. A team that publishes the framework before the first AI-graded report is a team whose compensation committee can defend the score. A team that publishes the framework after the first contested case is a team whose compensation committee is fighting from behind. The 30-day shadow period is the safety net that lets the team learn the AI model's inflation pattern before the score has consequences.
Why the productivity inflation effect shows up
A 2024 Harvard Business Review analysis of telemetry from more than 3,200 sales reps across SaaS, financial services, and industrial verticals concluded that productivity governance must precede productivity scoring. The documented control set defines what counts as rep-authored activity before the AI model scores it. The HBR team puts the recommendation bluntly: governance first, scoring second, compensation third.
HubSpot's State of Marketing 2025 report adds the operational evidence — sales organisations using AI-driven email drafting or AI-summarised call notes reported a 2.3x lift in logged rep activity volume but only a 0.4x lift in attributed pipeline versus control teams. Activity-quality scoring that does not separate rep-authored from AI-generated actions overstates productivity by an average of 28%. That 28% is not noise. It is the difference between a productivity conversation the team can defend and a productivity conversation that triggers a compensation dispute the company cannot win.
The reconciliation line is the highest-leverage intervention
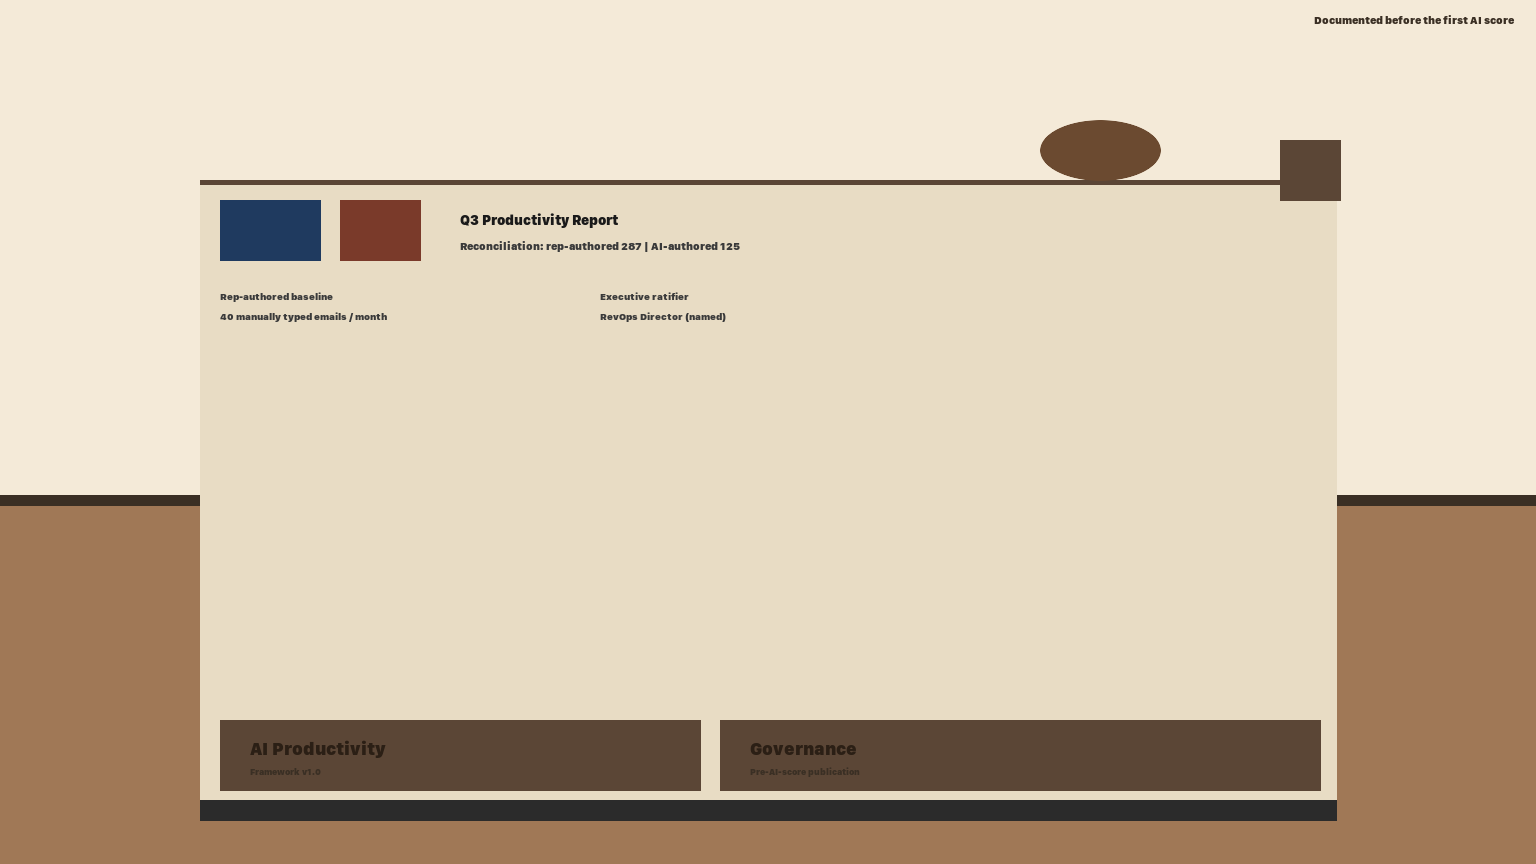
The reconciliation line is the highest-leverage transparency intervention a sales leader can ship. It is one column in the productivity report — call it the AI-authored-vs-rep-authored split — that says, of the 412 logged activities this rep produced this quarter, 287 were rep-authored and 125 were AI-authored. The column does not judge either bucket. It does not subtract the AI-authored activities from the score. It just publishes the count, so the reader of the report can decide whether the score reflects rep work or model work.
HBR found that compensation committees that received an AI-graded productivity score without the reconciliation line reversed the score in 41% of contested cases on first review, versus 7% when the reconciliation line was present. The reversal rate is the proxy for trust. The reconciliation line is what moves the proxy.
The rep-authored baseline
The baseline is the second control. Activity-quality scoring requires an explicit minimum set of rep-authored artifacts that a rep must produce before any AI-assisted signal counts. A reasonable baseline for a mid-market SaaS AE looks like this: at least 40 manually typed outbound emails per month, at least 20 manually logged discovery or qualification calls per month, and at least 8 manually created net-new opportunities per quarter. The baseline is not a quota. It is a guardrail that says the AI score is published only after the rep-authored floor is met.
Without the baseline, the AI model regresses to volume. With the baseline, the AI model has something to evaluate beyond how many Salesforce rows it could create on the rep's behalf.
Named executive ratifier and the human-review gate
The named executive ratifier is the third control. The ratifier is the person — usually the head of sales operations, the chief revenue officer, or a designated RevOps director — who signs off on the productivity framework, reviews the reconciliation line quarterly, and adjudicates any contested AI-graded score. The ratifier is not a committee. The ratifier is a single named human who can be held accountable for the framework's integrity.
HubSpot's data is direct on the impact: sales leaders who require an explicit human-validation step before AI-authored activities enter the productivity score saw 14% lower PIP noise and 9% higher forecast accuracy on a 12-month rolling basis. The 14% and 9% are not magic numbers. They are the operational cost of skipping the ratifier.
The documented human-review gate is the fourth control. The gate is the protocol the named ratifier follows when an AI-graded productivity score flags a rep for a compensation or PIP conversation. The protocol has three steps: open the reconciliation line and check baseline compliance; sample 25 random AI-authored activities to confirm the model did not misclassify rep-authored work as AI-authored; write a one-page summary of the review to the compensation committee regardless of outcome.
The written framework and the 30-day shadow period
The written framework is the fifth control, and it is the one that ties the other four together. The framework is a controlled document, not a slide deck. It names the reconciliation line, the rep-authored baseline, the executive ratifier, the human-review gate, and the cadence (quarterly at minimum, monthly for the top-decile teams). The framework is published before the first AI-graded productivity report is shared with compensation or PIP conversations.
The recommended adoption cadence is a 30-day shadow period followed by ratification. In the shadow period, the AI-graded productivity report is generated but not shared with compensation. The ratifier reviews the reconciliation line, the baseline compliance, and the human-review gate against historical rep activity. After 30 days, the ratifier publishes the first AI-graded score through the human-review gate, audits the reconciliation line for accuracy, and promotes the framework to all revenue teams.
NIST's AI Risk Management Framework Measure function adds the regulatory framing. Measure 2.3 in the NIST AI RMF Playbook requires that AI system measurement must include separate metrics for the model's performance and for the human contribution; a single blended score that hides human-AI attribution is insufficient for consequential decisions. The five-control governance schema is the policy that satisfies the NIST framing in vocabulary a compliance team can map to an internal policy.
Framework evolution and the conversation change
The framework is not a one-time artefact. The reconciliation line definition will drift as the AI model learns to draft better emails. The rep-authored baseline will need to be revised as the model takes on more activities. The named ratifier will rotate as the team grows. The human-review gate will be refined as edge cases emerge. The written framework is the artefact that holds the other four together across these revisions, and the quarterly review of the framework is the artefact that keeps the other four honest.
Sales leaders who have published the framework report that the conversation changes. The rep stops arguing about whether the AI score is fair and starts asking how to improve the rep-authored baseline. The compensation committee stops reversing scores and starts trusting the reconciliation line. The regulator, the board, and the plaintiff's attorney stop asking whether the AI productivity programme is defensible and start asking how the company got ahead of the inflation effect. The framework is what produces that conversation change, and the conversation change is what produces the 14% lower PIP noise and the 9% higher forecast accuracy that HubSpot measured.
Frequently asked questions
What if the rep-authored baseline is too aggressive for the role?
Set the baseline at the level the historical rep activity suggests and tune at the first quarterly framework review. A too-aggressive baseline is a recoverable calibration problem; an undocumented baseline is an unrecoverable audit problem.
What if the named executive ratifier is unavailable?
Name a backup in the framework document. A ratifier without a documented backup is a single point of failure that the framework was designed to eliminate.
How does the reconciliation line interact with compensation?
The reconciliation line is published alongside every AI-graded score that reaches a compensation or PIP conversation. The line does not modify the score; it makes the score auditable.
Does the framework apply to non-sales roles?
The five-control schema is editorial framework; the same structure applies to any AI-graded productivity report where the AI model and the human contributor are conflated without a documented separation.
SOURCES & EDITORIAL NOTE
This article is an editorial framework, not a legal or compensation advisory, and it deliberately borrows no benchmarks. The governance-first sequencing comes from HBR's analysis of sales-rep productivity in the age of AI (ev-aisrpg-002); the activity-volume vs attributed-pipeline operational evidence from HubSpot's State of Marketing 2025 (ev-aisrpg-003); and the separate-metric discipline from NIST AI RMF Playbook Measure 2.3 (ev-aisrpg-004). All sources were fetched and verified on 2026-09-20. The reconciliation line, rep-authored baseline, named executive ratifier, documented human-review gate, and written framework are SellersGPT editorial recommendations and starting points. Related reading: AI SDR vendor exit plan, AI sales engagement reply state machine, AI lead enrichment lineage audit.
MORE PRACTICAL IDEAS FOR B2B GROWTH
Related Articles
BUILD A PIPELINE THAT YOUR TEAM CAN SEE
Find more B2B buyers-without building a bigger team first. Tell us what you sell, which markets you want to reach, and what should count as a Qualified Lead. We'll help you build a repeatable path to the right buyers.